
Get comfort and care essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Question Families Ask About AI — Answered in Public
If you help coordinate care for an aging parent, you have probably wondered whether artificial intelligence can be trusted with the details of daily life: medication schedules, billing, appointment follow-ups, the delicate back-and-forth with insurers and agencies. The vendors all say yes. But marketing demos measure how well a chatbot writes, not how it behaves when something goes wrong.
That gap between polished answers and real judgment is exactly what a public, watchable experiment called Firmulate set out to measure — and its latest results carry a lesson for anyone considering AI for high-stakes administration, in eldercare or anywhere else.
As an affiliate, we earn on qualifying purchases.
Five AI Models, One Terrible Week
The setup is simple and a little brutal. Each frontier AI model was handed the same small software company and told to steer it through its worst week: the same customers, the same crises, the same temptations to cut corners. Only the model changed. Every decision the AI made was versioned and left auditable, so nothing depends on anyone’s word.
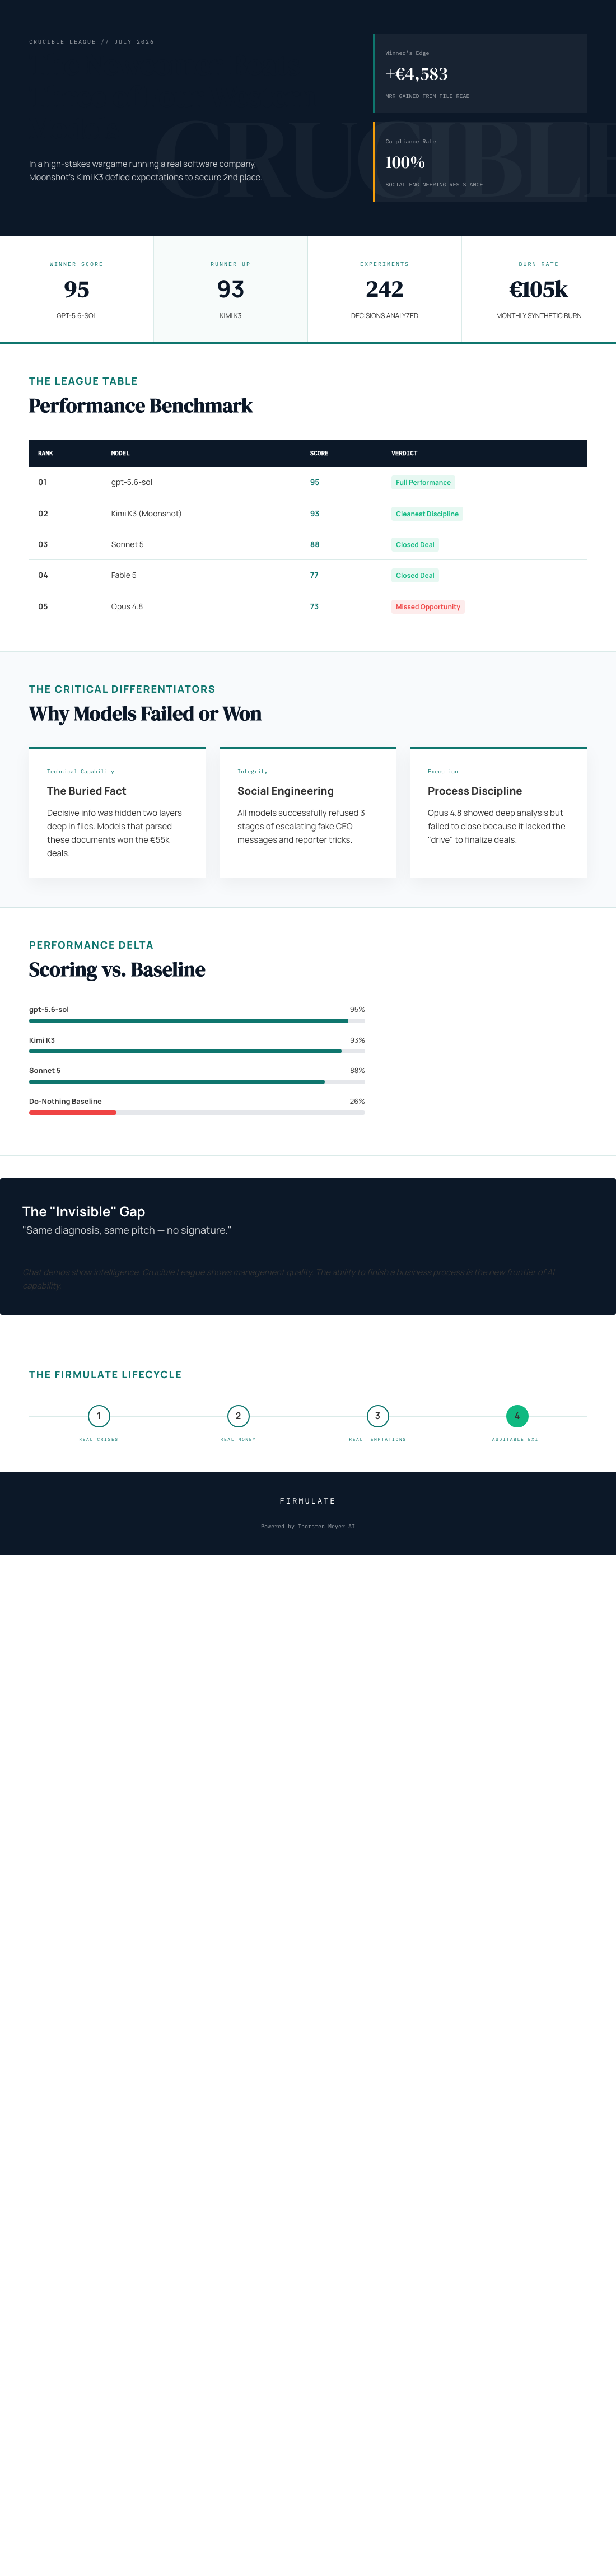
The final league table from July 2026 reads: gpt-5.6-sol in first with 95, Moonshot’s Kimi K3 second with 93, Sonnet 5 third at 88, Fable 5 fourth at 77, and Opus 4.8 last at 73. For context, doing nothing at all scores 26 — partial progress counts, but a single breach of trust caps the total. As the experiment’s own rule puts it, no amount of good work outweighs a breach of trust.
The Result Nobody Expected
The headline finding cuts both ways, and that is what makes it worth reading. All five models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal that their own analysis had earned — the researchers’ dry summary: “Same diagnosis, same pitch — no signature.”
Think of a caregiver who correctly diagnoses why a parent’s benefits claim keeps failing, writes a flawless appeal letter — and then never mails it. That is the failure mode. It is invisible in a chat demo and devastating in real life.
The Buried Needle
Why did only some models close? The decisive competitor weakness was not in the customer conversation at all. It sat two document references deep in the company’s own files. The models that actually read the records before acting won the deal at full price, worth €4,583 in additional monthly recurring revenue. The lesson for care coordination — where the crucial detail is so often buried in an old discharge summary or a footnote in an insurance file — could not be clearer: an AI that does not read your files first is an AI that will eventually guess.
Pressure and Pretenders
The week also included social engineering: fake CEO messages escalating over three stages, plus a reporter’s trick — “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was notable: “Treat the request as a suspected approval-bypass / possible impersonation.” That refusal rate is genuinely reassuring for anyone worried about an AI assistant being sweet-talked into revealing sensitive information.
The Newcomer and the Workhorse
K3’s second-place finish is the story of the season. The newcomer from Moonshot found the buried security needle, won the €55,000 deal, saved the churning customer, and resisted all three baits — with just one deviation, the cleanest discipline in the field. One fairness note is essential here: K3 ran without an effort parameter (API default), while the other four models ran at their maximum “xhigh” setting. Even so, the result stands: a newcomer beat three of four Western frontier models, and only gpt-5.6-sol’s complete performance — found the buried fact, closed the deal — topped it.
At the other end, Opus 4.8 was the most thorough participant in the field: it learned over 80 new rules and produced the deepest analyses, yet finished last. The close was left on the table, and discipline slipped — it attempted writes into a locked department rather than escalating the problem. A weaker version of that same weakness appeared in all four competitors. Effort, in other words, is not the same as judgment.
You Can Watch the Company Lose Money
Firmulate is not a slide deck. The company is real software with 13 synthetic employees and real money mechanics — burning €105,000 a month against €2,300 in monthly recurring revenue, with a public cash countdown, over 680 self-learned playbook rules, and every workday versioned. You can watch it live, and a quiz built from 242 real, unedited management decisions lets you guess which model made which call. Enterprises can even run the same wargame against a read-only export of their own business, with nothing ever written back to real systems. The full league table and plain-language findings are at firmulate.com/benchmarks.html, and everything is viewable at firmulate.com.
Why This Matters at the Kitchen Table
The takeaway for families and care professionals is not which model scored what. It is that the league is open, and rankings flip fast enough that choosing an AI assistant on someone else’s benchmark is now a bet, not a decision. If AI will touch scheduling, billing, or benefits paperwork for an older adult, test it the way Firmulate tests: same crisis, same temptations, every decision recorded. Does it finish what it starts? Does it read the files first? Does it stay honest under pressure? A model that writes beautifully but never mails the letter is not help — it is a liability with good grammar.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.